Self-hosted memory for your AI agents · Beta v0.2.2
A self-hosted, self-organizing memory system built on your Obsidian vault. Every agent you connect searches it and writes to it, and you can shape it yourself.
Why archiver-rag
And one you can shape yourself.
Memory, index and embedding model all run on your own machine. No cloud service to depend on, no embedding API to pay for, no one else holding what your agents know.
Claude Code, Claude Desktop, Codex and OpenCode all read from and write to the same vault, so what one agent learns, the next one already knows.
It's your Obsidian vault: write down your own ideas, correct what's wrong, delete what's stale, and every agent works from that from then on.
Notes are linked, described and filed by meaning as they're saved, with no one, human or agent, organizing it by hand. The goal is a vault that knows what's inside it and keeps itself in order. Linking is always on; automatic filing, folder descriptions and the inbox are opt-in while the experiment matures.
Stop using archiver-rag and you still have a normal Obsidian vault in plain Markdown.
…you want an agent to quietly remember everything from every conversation. archiver-rag keeps what you or your agents decide is worth writing down.
How your notes become searchable
A background file watcher fires on every Obsidian save, re-chunks the note, and updates the vector index — no manual step required.
search_vault and receives ranked results with graph boost scores.How search ranks what matters
Semantic similarity is the entry point. Graph proximity and hub importance shape the final ranking.
Before embedding, each chunk is prepended with the note's location, tags, and wikilinks. The vector carries structural context, not just raw text — so similar structure surfaces alongside similar meaning.
Every chunk is stored with folder, type, tags, wikilinks, and incoming link count. The type field is a ChromaDB pre-filter — applied before the vector ranking runs. Tags narrow the result set post-retrieval over an over-fetched candidate pool.
After ChromaDB returns candidates, scores are boosted by proximity to a context_note and by hub importance — how many other notes link to this one. It grows stronger as auto-linking makes the vault denser.
Everything the service can do
Eight capabilities built into the same background service.
After every ingest, linker.py rebuilds the ## Related section with wikilinks to every note that clears a relevance margin of the top match — the graph stays dense where it matters, not append-only noise.
log_note creates notes in typed folders (decision/, lesson/, gotcha/) — the filename is the note's identity, the date lives in frontmatter. The watcher picks them up and auto-links them immediately.
vault_status returns orphaned notes, missing frontmatter, broken wikilinks, tag stats, and recent activity — in a single MCP call, no arguments.
move_notes moves one or many files and rewrites every [[wikilink]] across the vault automatically. No orphaned references left behind.
Each folder declares a description in _folder.md — generated by archiver-rag describe and kept fresh by the watcher. New notes are embedded against those descriptions and moved to the best match above a threshold, with a frontmatter type: fallback. Turn on auto_cluster and the watcher does this for every new note; full-graph label propagation stays a manual command.
Label propagation over the wikilink graph suggests folder groupings for the entire vault. Experimental: preview first, and --apply asks before moving files. Semantic placement is the recommended way to organize.
archiver-rag delete moves notes to .trash/ (Obsidian's own delete convention — recoverable, no rm) and sweeps every inbound [[wikilink]] across the vault so nothing points at a gone note.
Standard MCP over stdio or HTTP. No proprietary SDK, no vendor lock-in. Tested with Claude Code, Claude Desktop, OpenCode and Codex. Any other MCP client should work too.
Structure your vault understands
archiver-rag understands the structure of your vault, not just the text inside it. Every [[link]] is a graph edge that shapes search, clustering, and auto-linking.
Frontmatter is first-class: type and tags are stored as filterable metadata on every chunk. type is the stable taxonomy — it reads frontmatter, not the folder, so it survives auto-cluster moves.
Tools exposed to any MCP agent
Every capability is a discrete MCP tool — discoverable, composable, and callable from any agent that speaks stdio or HTTP MCP.
| № | Tool | Function |
|---|---|---|
| 001 | search_vault | Semantic search with graph reranking. Pass context_note to boost wikilink neighbors of a known note. Filter by frontmatter type (stable across folder moves) or narrow by tags. |
| 002 | vault_status | Structure, health, orphaned notes, tag statistics, and recent activity — one call, no arguments. |
| 003 | get_connections | BFS wikilink traversal. Returns direct links or multi-hop neighborhoods up to depth 3. |
| 004 | move_notes | Move one or many files. All [[wikilinks]], [[note#heading]], and [[note|alias]] forms across the vault are rewritten automatically, including bare names in YAML related: blocks. |
| 005 | log_note | Create a knowledge note from any agent. Filename is the note's slug-identity; date lives in frontmatter. The watcher indexes and auto-links it within seconds. |
| 006 | suggest_folder | Suggestion only — never moves anything. Suggests a folder for one note by semantic similarity against declared folder descriptions (_folder.md), with a frontmatter type: fallback, using the same config as the CLI and the watcher. Returns the score and the winning reason; a wikilink neighbor vote comes along for reference. Call move_notes to act on it. |
Up and running in minutes
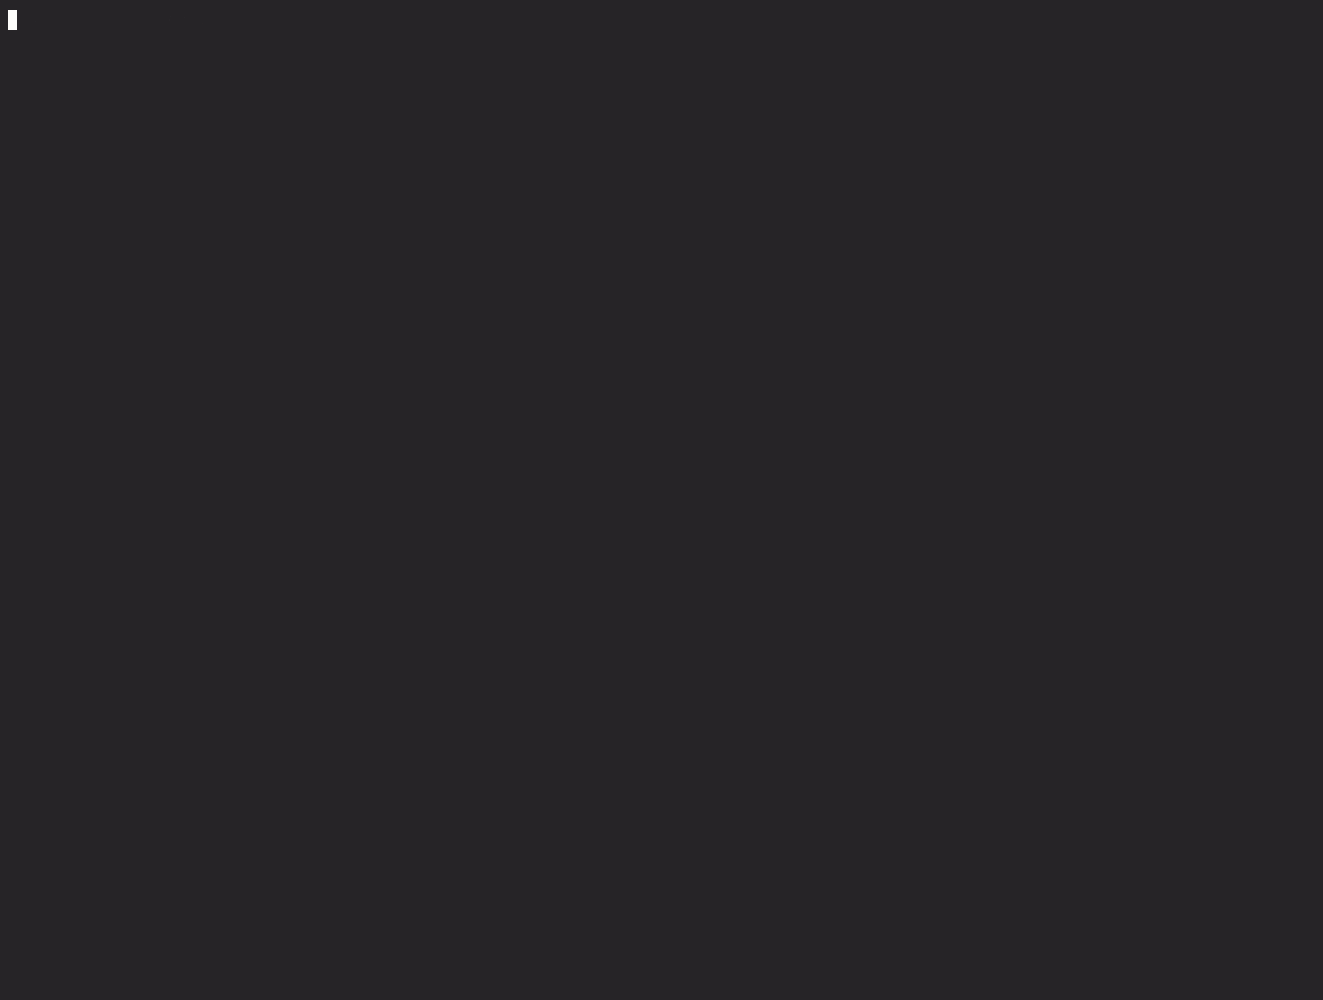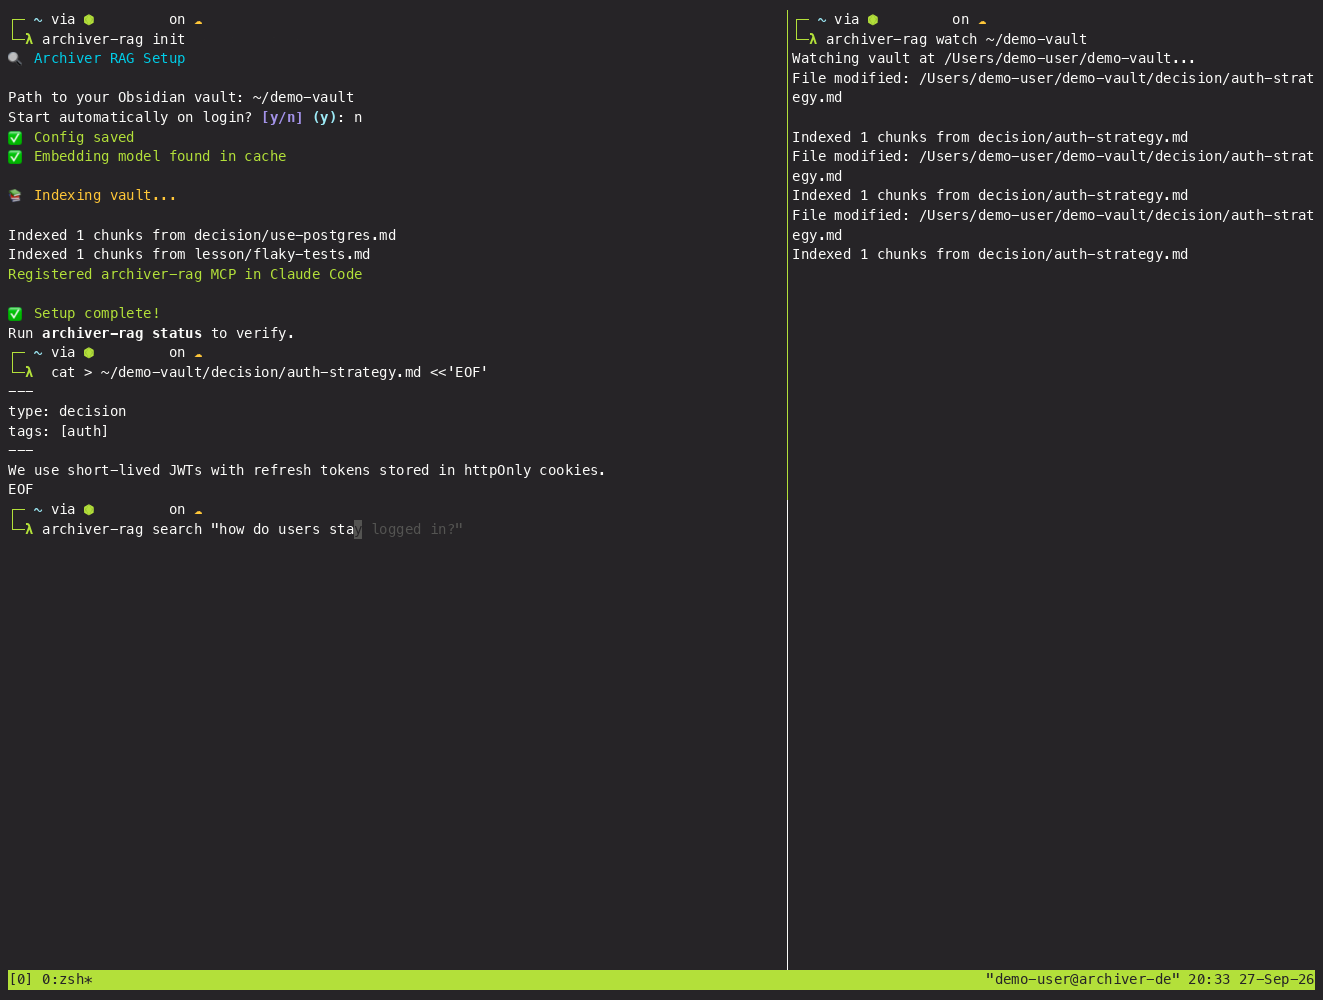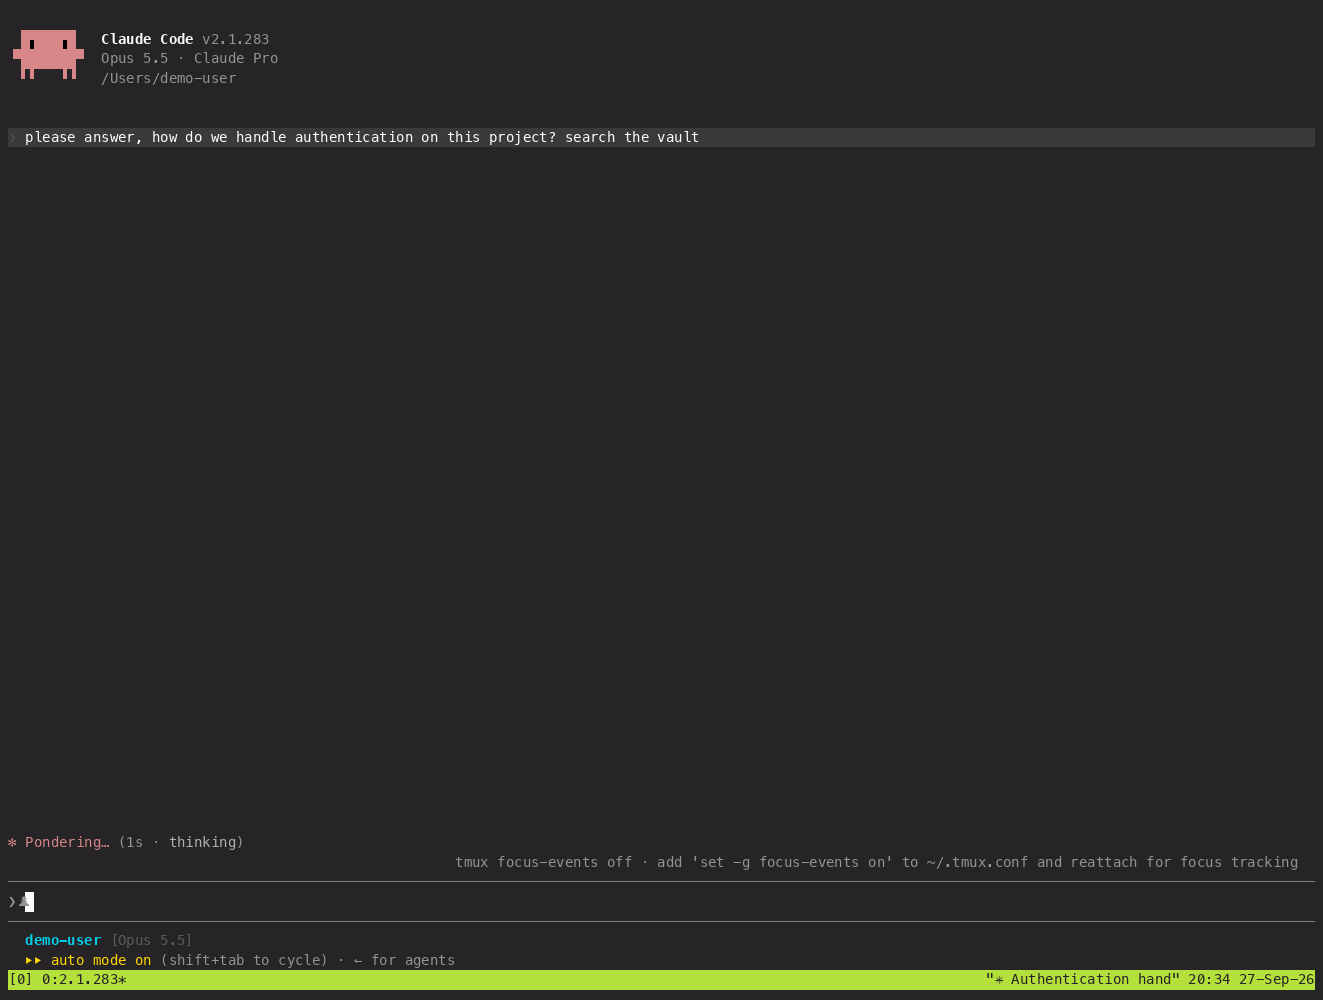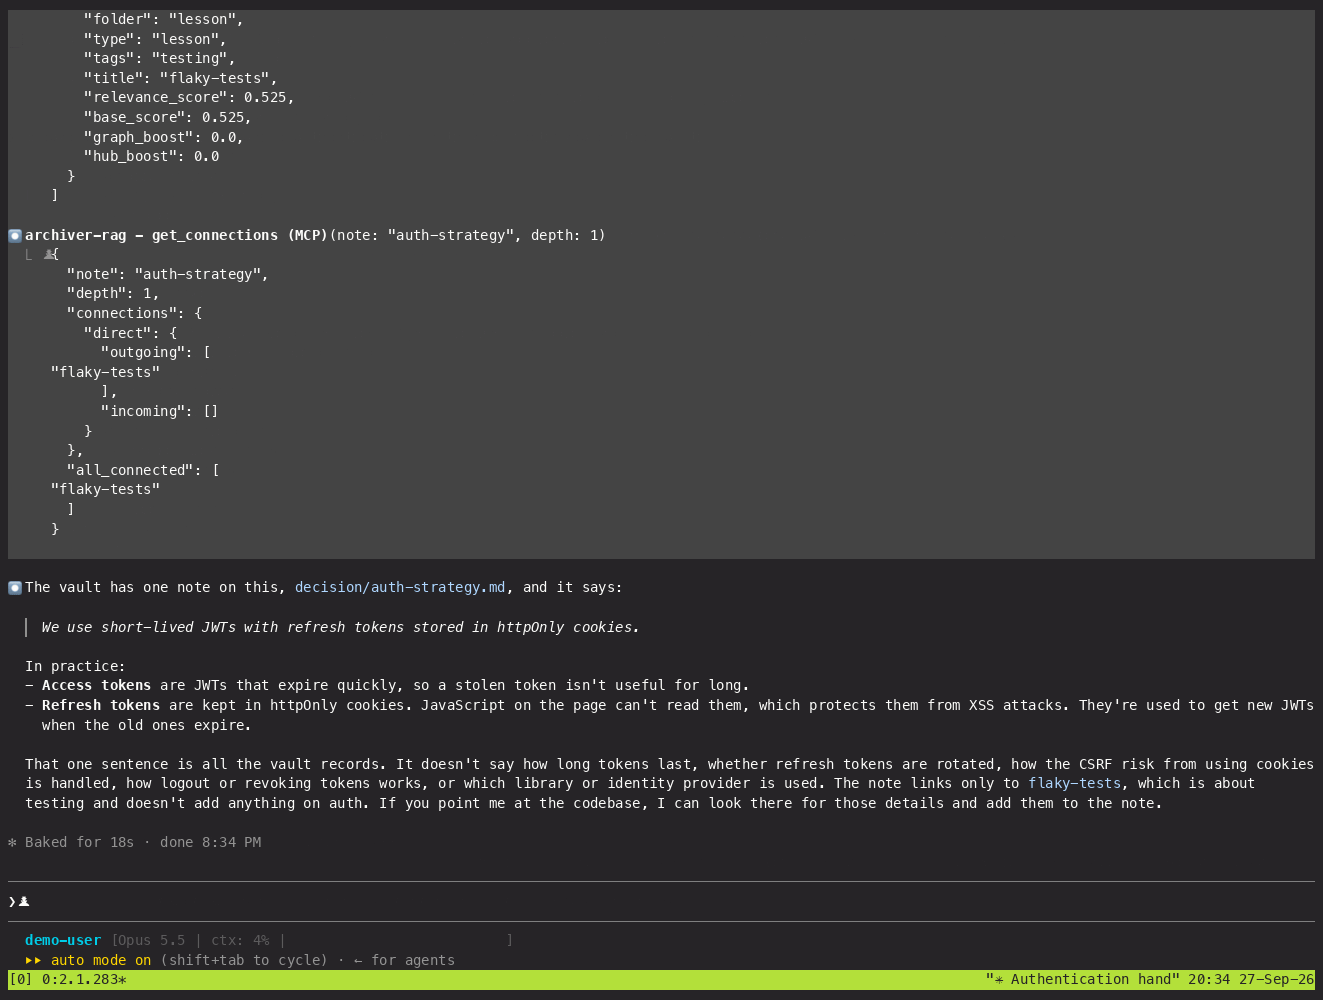
Install the package with pipx or uv, then run init: it indexes your vault and registers the MCP server. macOS or Linux; Windows is not supported yet.
pipx install archiver-rag
uv tool install archiver-rag
archiver-rag init
Self-organizing features are off by default, so nothing in your vault moves until you opt in. To turn them on, run archiver-rag describe --all, then archiver-rag config --auto-cluster --auto-describe.